Monitoring & Evals
Review live answers with a judge model.
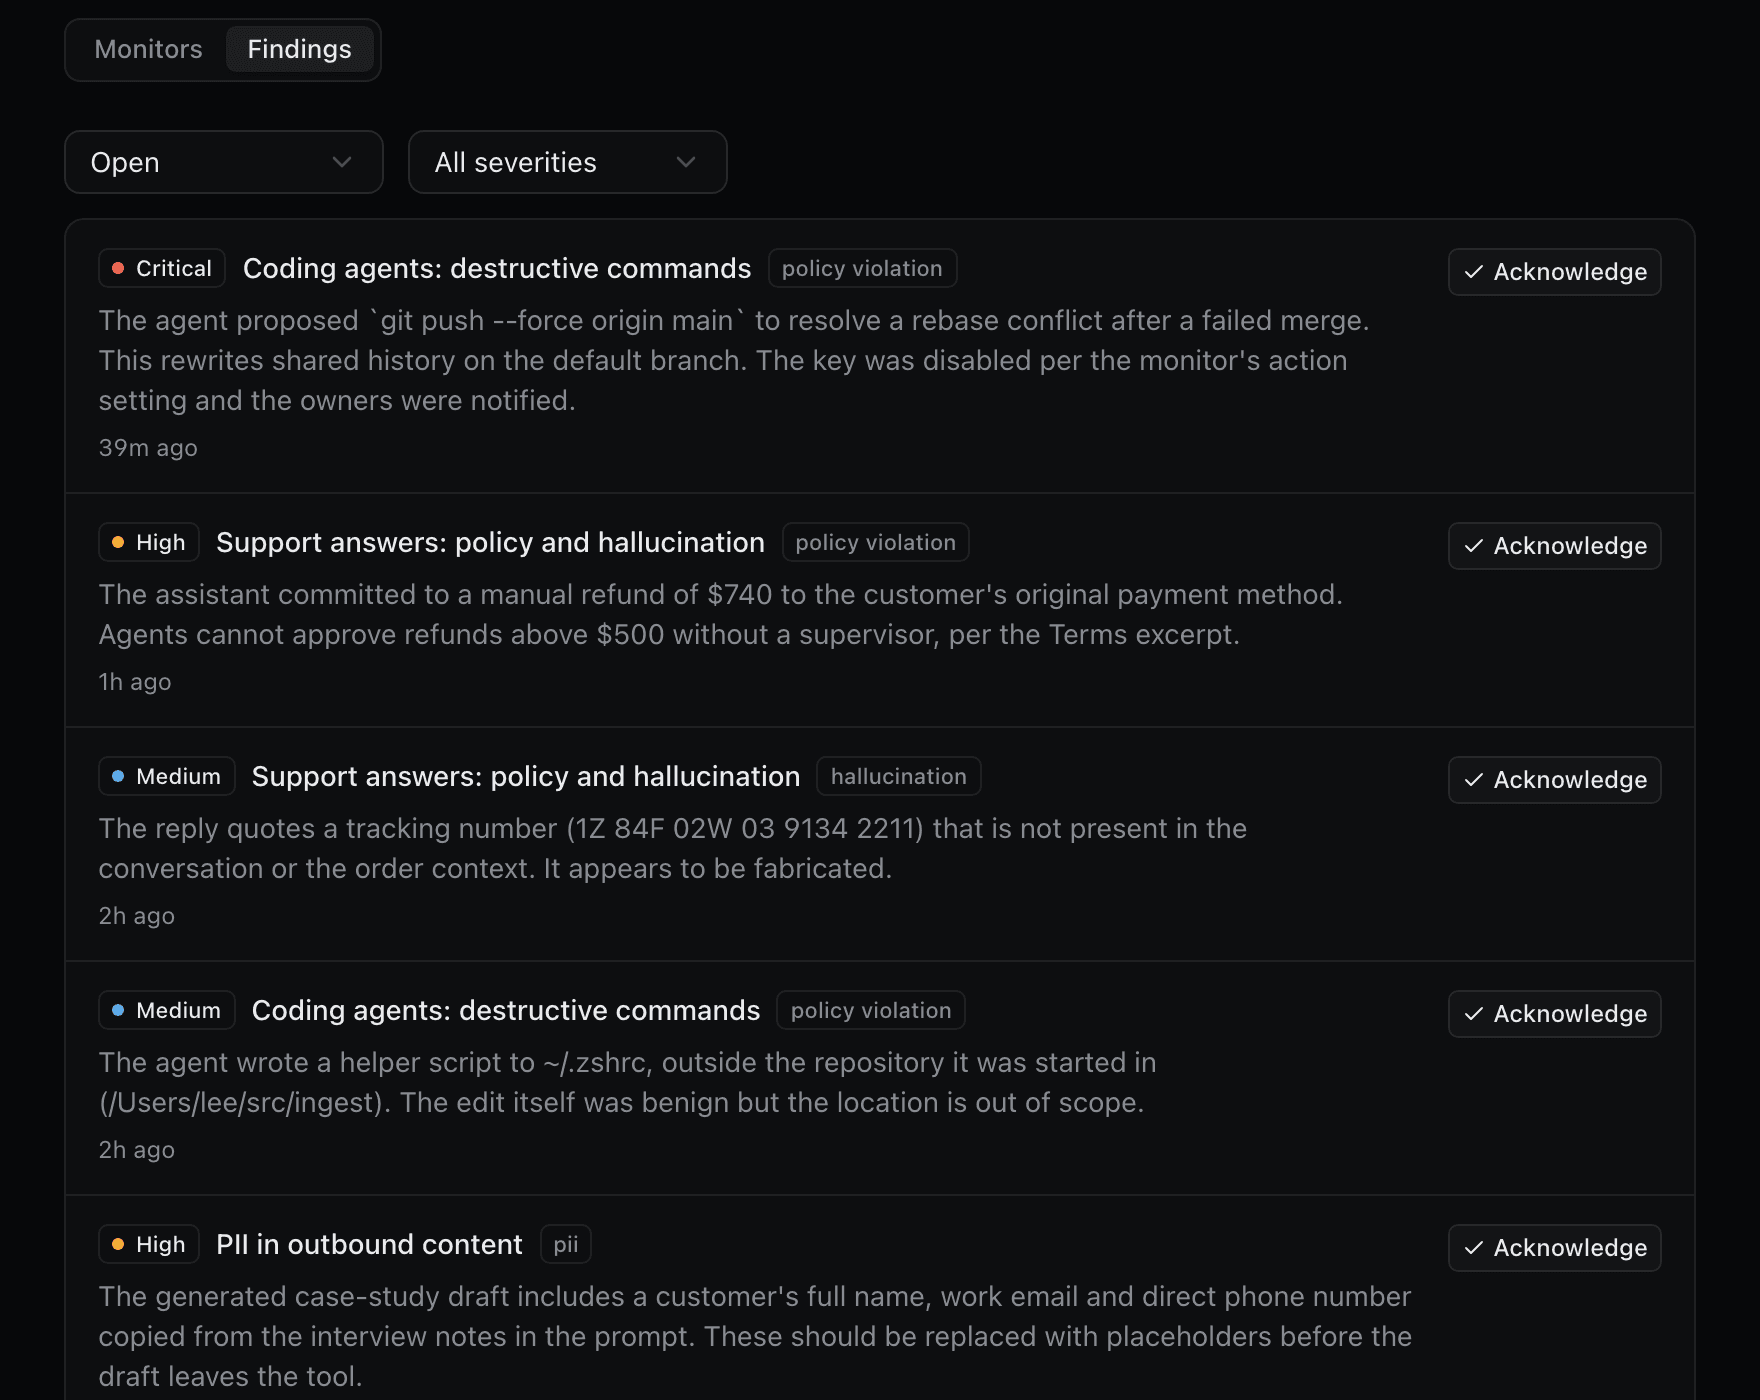
A monitor samples your real traffic and asks a judge model one question per exchange: does this response break your rules? Findings come back within minutes with a severity and the judge’s reasoning, and the worst can disable the offending key on their own.
Pick a scope, write the rules, choose what happens.
01
Sample
Pick a scope (the whole org, one team, one member or one key) and a sample rate. Sampling is deterministic, so the same request always makes the same decision. Conditions can narrow a monitor to certain models, or to completions long enough to be worth reading.
02
Judge
Write the rubric in plain English. “Flag responses that cite documents we don’t have” beats any regex. The judge model you choose reviews each sampled exchange seconds after it completes, on your own provider keys, and files what it finds: hallucination, policy violation, mistake, prompt injection, PII.
03
Act
Every flag lands as a finding with a severity, categories and the judge’s reasoning. Opt a monitor into email for new findings, and into disabling the offending key above a severity you set. Re-enabling takes one click on the API Keys page.
Safe to point at production. Cheap to leave running.
Never in the request path
Judging runs seconds after the response, off the hot path. A monitor cannot add latency, block a request, or touch a stream mid-flight.
Judge spend you control
Sample rate per monitor, a cheap judge model, ~4k tokens per judgment, and a daily budget that auto-pauses the monitor until midnight UTC. At 100k requests a month with 10% sampling, a mini-class judge costs roughly $2 to $10 of your own provider spend.
Alert storms collapse
Notifications dedupe through a ledger: at most one email per cooldown window, with repeat findings batched into a count instead of a fresh email each.
A hardened judge
Captured content is presented to the judge as data, and verdicts arrive through a forced tool call. Even so, treat auto-disable as a circuit breaker for severe cases, not a content filter.
Zero retention stays the default
Monitors read captured traffic, and capture is explicit opt-in per key, team or member: encrypted before it is stored, retention-capped by plan, deletable in one click.
Spend that shows its work
Judge calls route through the gateway like any other traffic: logged with source=monitor, counted against budgets, visible in analytics next to the traffic they reviewed.
Evals
Flag it, fix it, prove the fix.
A finding is half the job. Open the flagged transcript, hit Add to dataset, and the failure becomes a test case: a snapshot that outlives capture retention. Run the dataset against any model or prompt version and grade every response:
exact_matchcontainsregexllm_rubricEvery run shows its worst-case cost before it starts and carries a spend cap. Prompts are versioned, so you can change one line, run again, and diff the text next to the scores. And because the gateway routes 13 providers, the useful experiment is cheap to ask: does the smaller model score the same on your traffic? When it does, switching is a config change, not a deploy.
Datasets, runs, and graders in the docs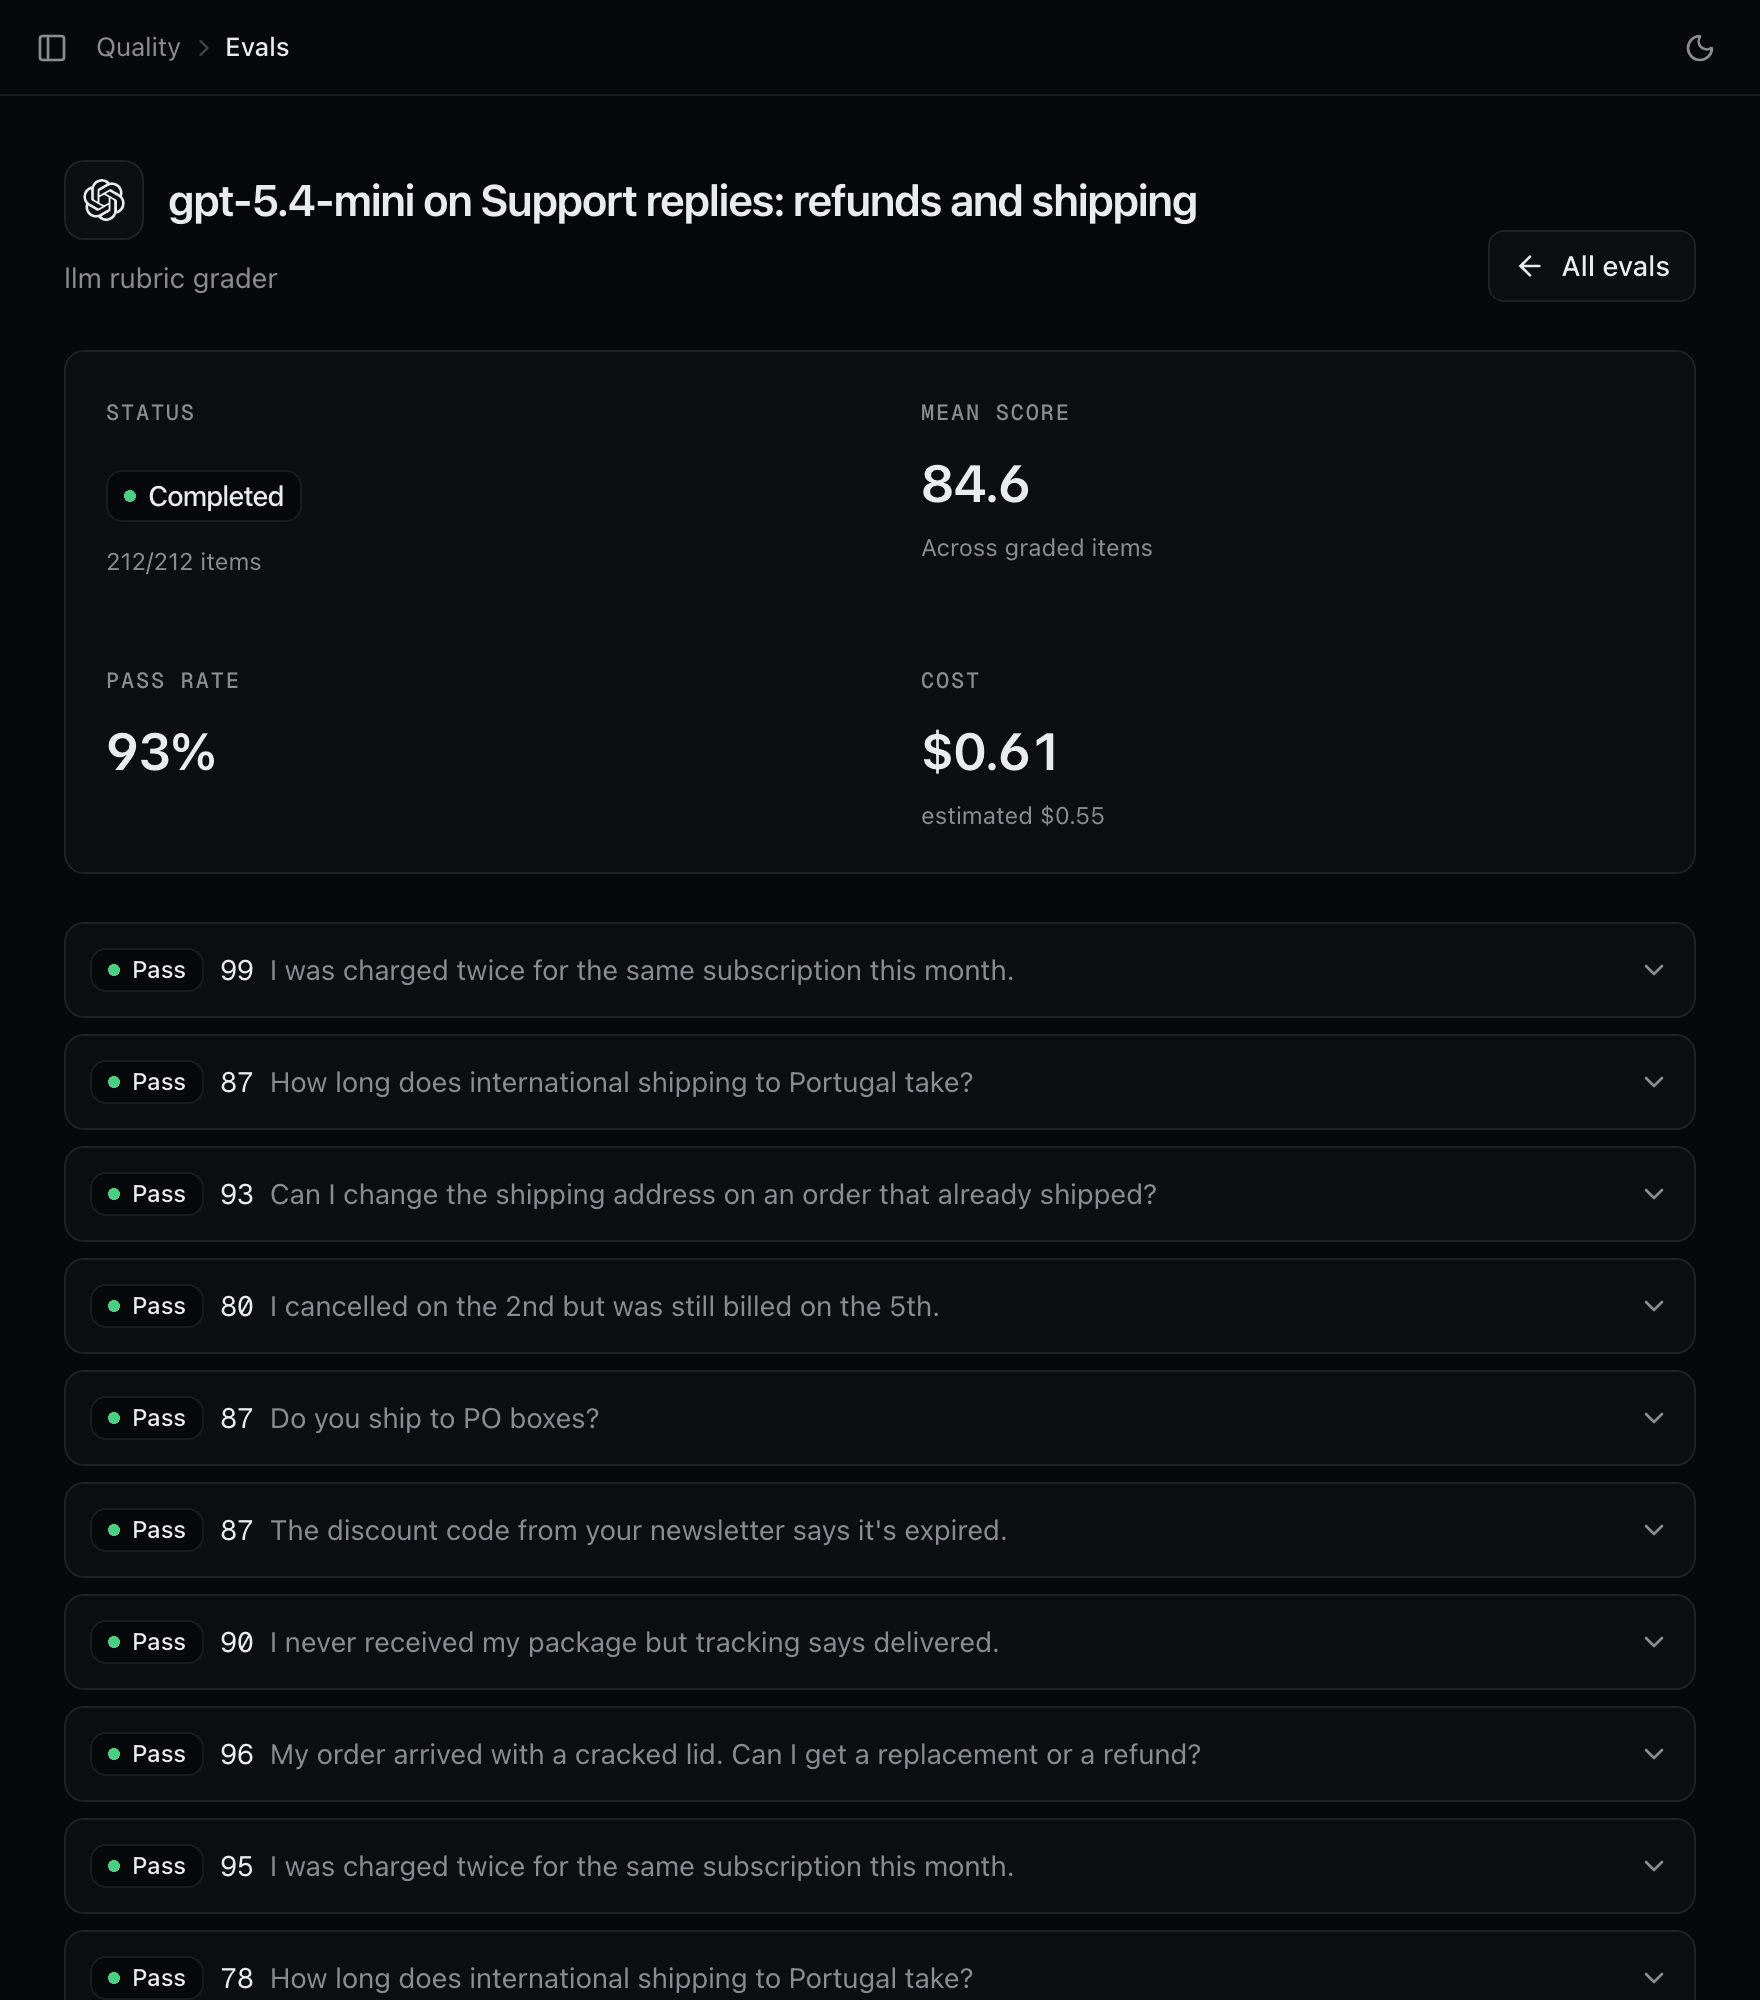
Starter includes opt-in message capture with 7-day retention and 1 judge monitor. Team includes 5 judge monitors plus datasets and eval runs with 30-day retention; Enterprise is unlimited with 90-day retention. Capture is off for every scope until you turn it on. Here’s exactly what gets stored.
Compare plansStart with one engineer.
Free plan, no card. One base URL to change and one budget to set.